Job Market Analysis Platform Screenshots.
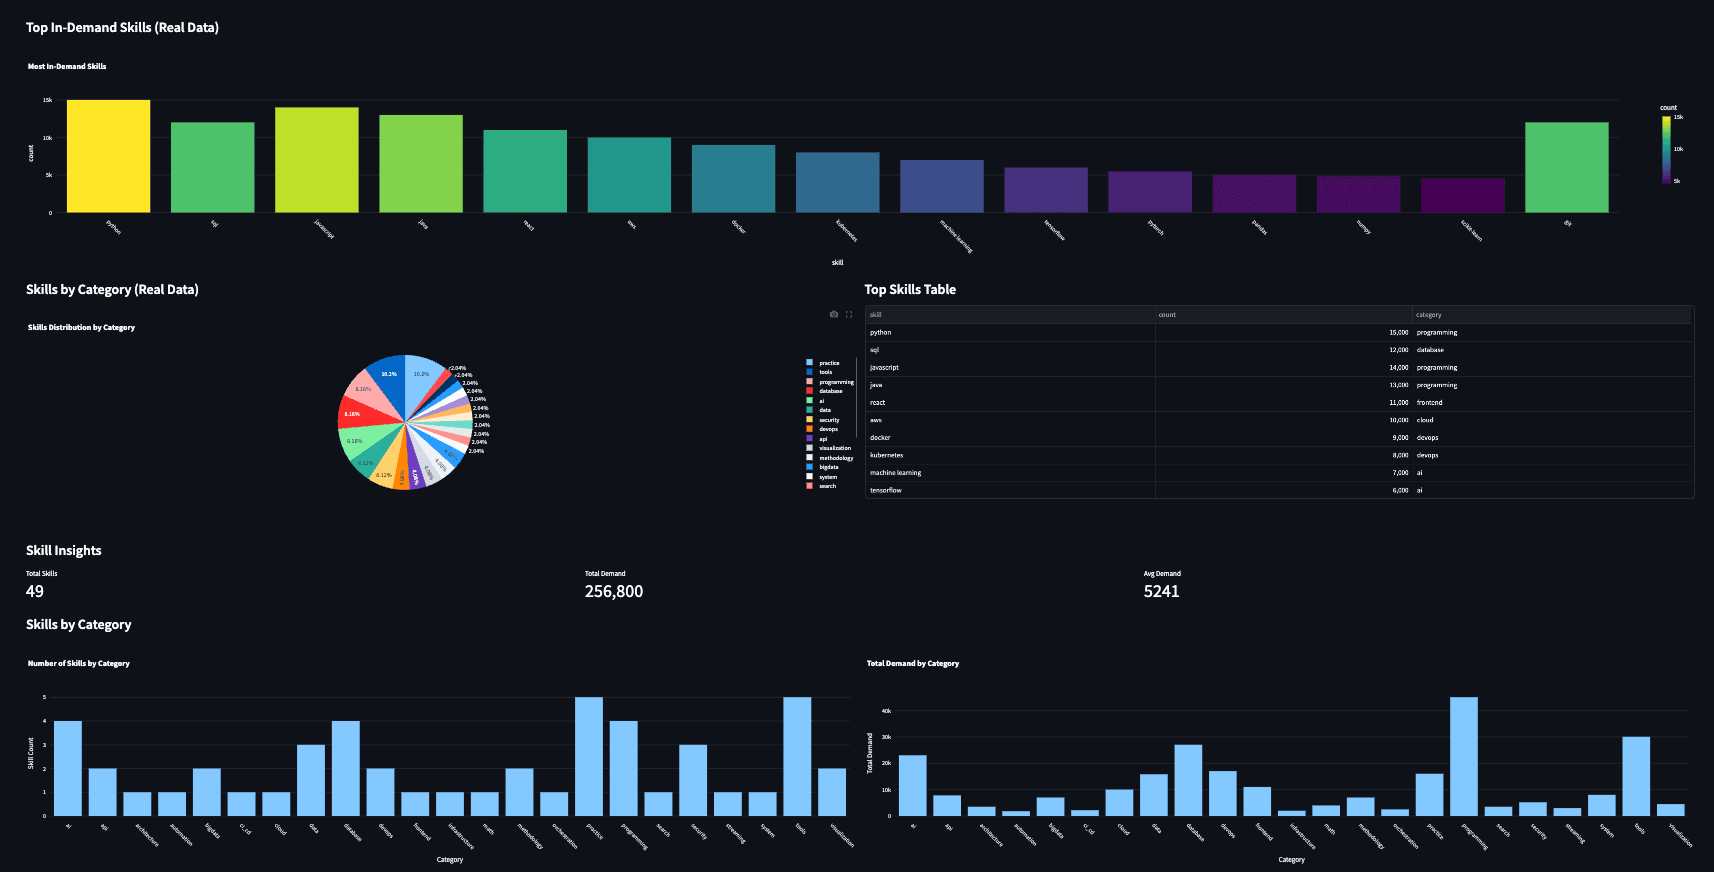
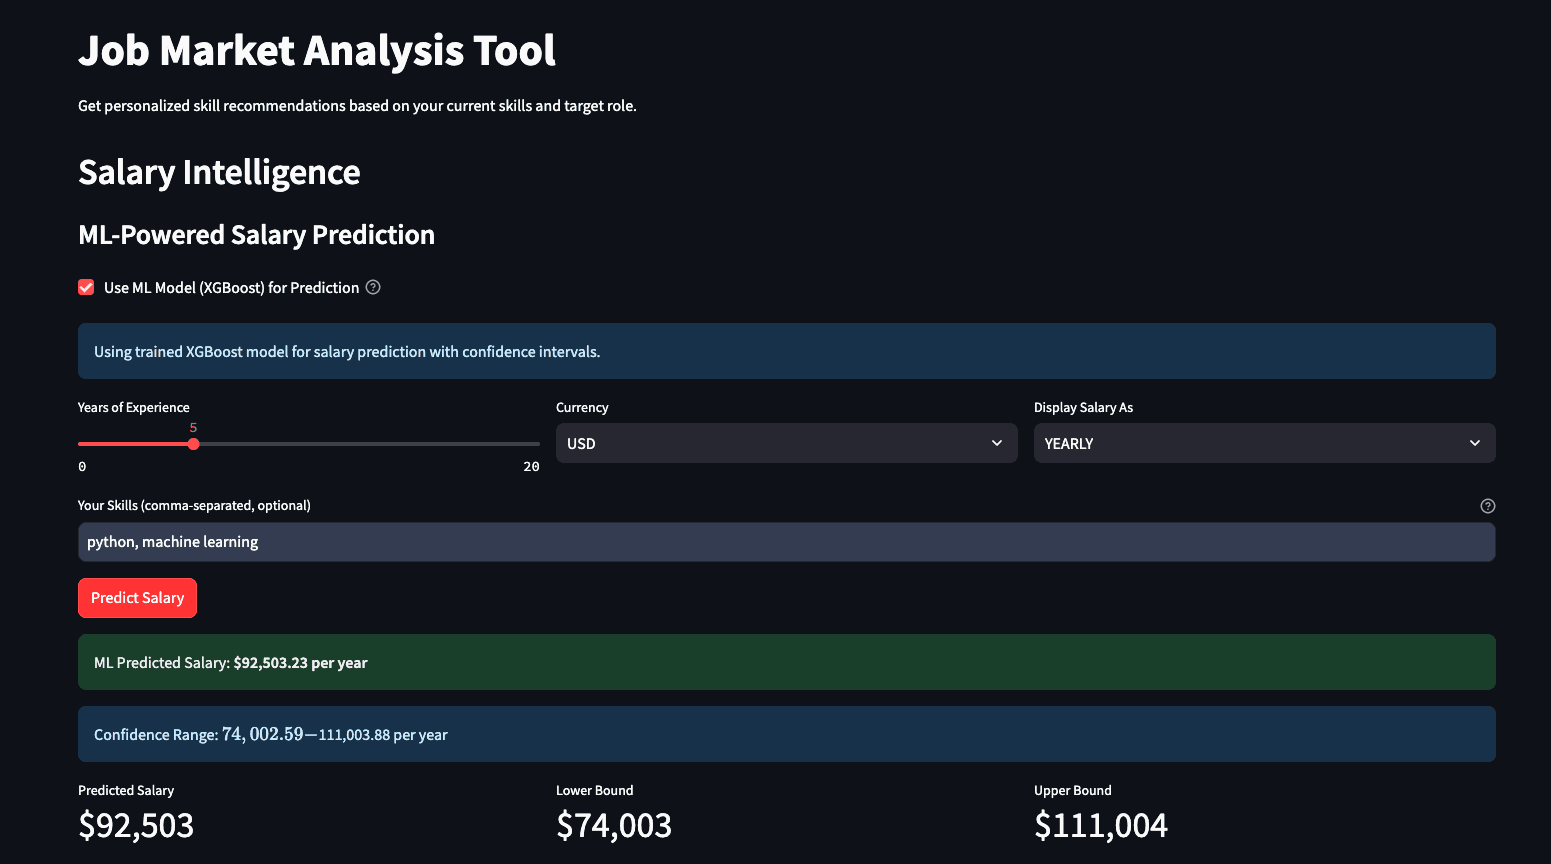
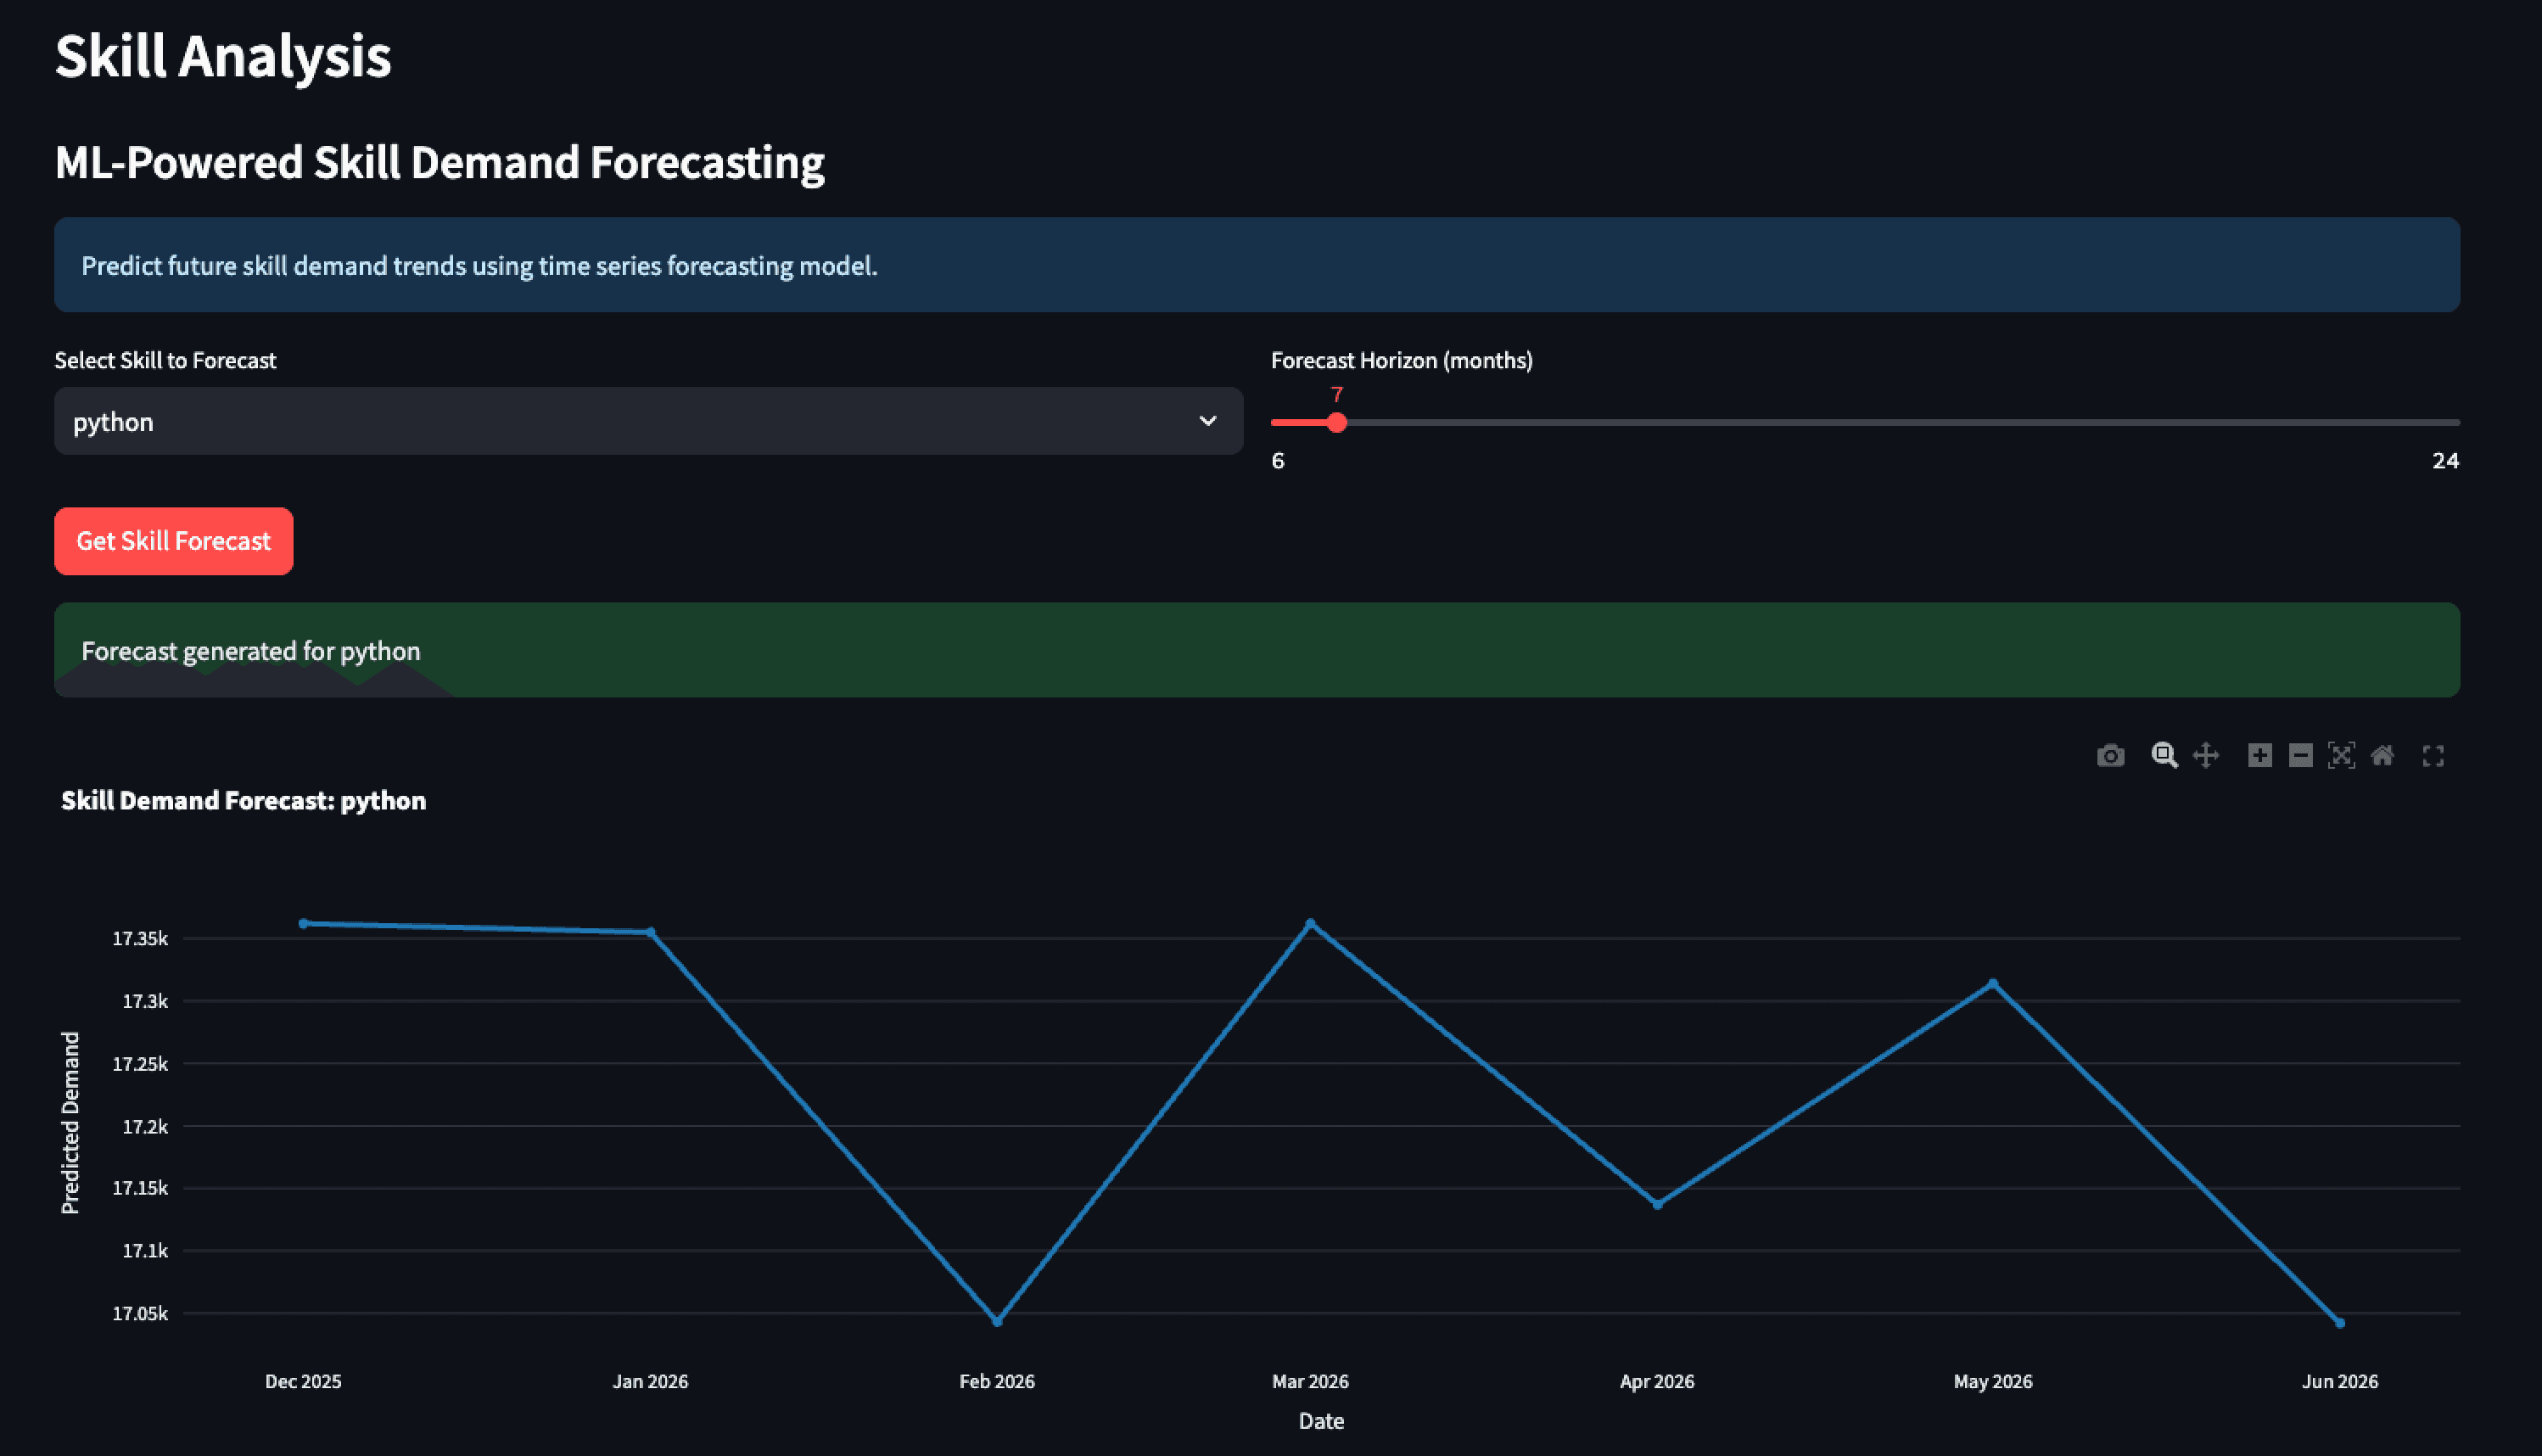
Overview
Enterprise-grade Big Data analytics platform analyzing tech job market trends, salary predictions, and skill demand forecasting. Processed 129.68 GB across 4 data sources with a 3-layer data lake and 2.7M+ records.
What I built.
- 013-layer data lake architecture (Raw/Bronze/Silver/Gold)
- 02Distributed batch + streaming processing pipelines
- 03Model tracking and experiment reproducibility
- 04Interactive analytics delivery with low-latency APIs
Solo-built big data starter for tech job market analytics. Data lake (Raw/Bronze/Silver/Gold) with 129+ GB from GitHub Archive, Kaggle, StackOverflow, and BLS. Apache Spark for distributed processing, Delta Lake for versioned storage, Airflow for orchestration, Kafka for streaming, MLflow for experiment tracking. FastAPI service with health check and salary endpoint; XGBoost salary prediction and skill forecasting.
Project details
In depth.
Project Structure
job-market-analysis/
├── data/                           # Data Lake Architecture (129.68 GB)
│   ├── raw/                        # Original data sources
│   │   ├── github/                 # GitHub Archive data (123.43 GB)
│   │   ├── kaggle/                 # Job market datasets (2.23 GB)
│   │   ├── stackoverflow/          # Developer surveys (0.88 GB)
│   │   └── bls/                    # BLS employment data (0.002 GB)
│   ├── bronze/                     # Cleaned and standardized data (3.14 GB)
│   ├── silver/                     # Unified datasets (0.004 GB)
│   └── gold/                       # ML-ready data
│
├── src/
│   ├── api/                        # FastAPI Application
│   ├── common/                     # Shared Utilities (logging, paths)
│   ├── etl/                        # ETL Pipeline (bronze → silver → gold, unified postings)
│   ├── ingest/                     # Data Ingestion (GH Archive, StackOverflow, BLS, large-scale GitHub collection)
│   ├── ml/                         # XGBoost salary model, skills trend forecasting, training pipeline
│   ├── spark/                      # Apache Spark ETL pipelines
│   ├── streaming/                  # Apache Kafka streaming demo
│   └── app_streamlit.py            # Main Streamlit dashboard
│
├── dags/                           # Apache Airflow DAGs
├── notebooks/                      # Exploratory Data Analysis
├── reports/                        # Comprehensive analysis report
├── models/                         # Trained XGBoost salary prediction model
└── mlruns/                         # MLflow experiment runs and artifacts
Key Features
Data Lake Architecture
- Raw Layer: 126.54 GB of original data from 4 sources
- Bronze Layer: 3.14 GB of cleaned and standardized data
- Silver Layer: Unified datasets across sources
- Gold Layer: ML-ready feature engineering
Big Data Tools
- Apache Spark: Distributed data processing
- Delta Lake: Versioned data storage
- Apache Airflow: Workflow orchestration
- Apache Kafka: Real-time streaming
- MLflow: ML experiment tracking
Machine Learning
- XGBoost: Salary prediction model
- Feature Engineering: Automated pipeline
- Model Serving: FastAPI endpoints
- Experiment Tracking: MLflow integration
API & Visualization
- FastAPI: REST API with 5+ endpoints
- Streamlit: Interactive dashboards
- Real-time Data: Live GitHub activity
- Predictive Analytics: Salary predictions
Tech specs
Under the hood.
- Apache Spark
- Delta Lake
- Airflow
- Kafka
- MLflow
- XGBoost
- FastAPI
- Docker
A complete data product story from ingestion to model serving to business-facing dashboards.